Icon ➜ Auto-Generated Tags
Splitting Perception from Decision (Part 2)
Sep 19, 2026
Introduction
In Part 1, two Adobe icon designers built a six-facet controlled vocabulary for a library of 30,000+ icons, and I promised a zero-shot vision-language model would start filling it in. This post keeps that promise — then breaks the system it describes. The VLM ran in production, and it works. What it cannot do is say when it doesn't know: a generative model has no honest confidence signal, and no prompt can add one. Without it, the pipeline has no principled way to decide which tags to trust and which to route to a human.
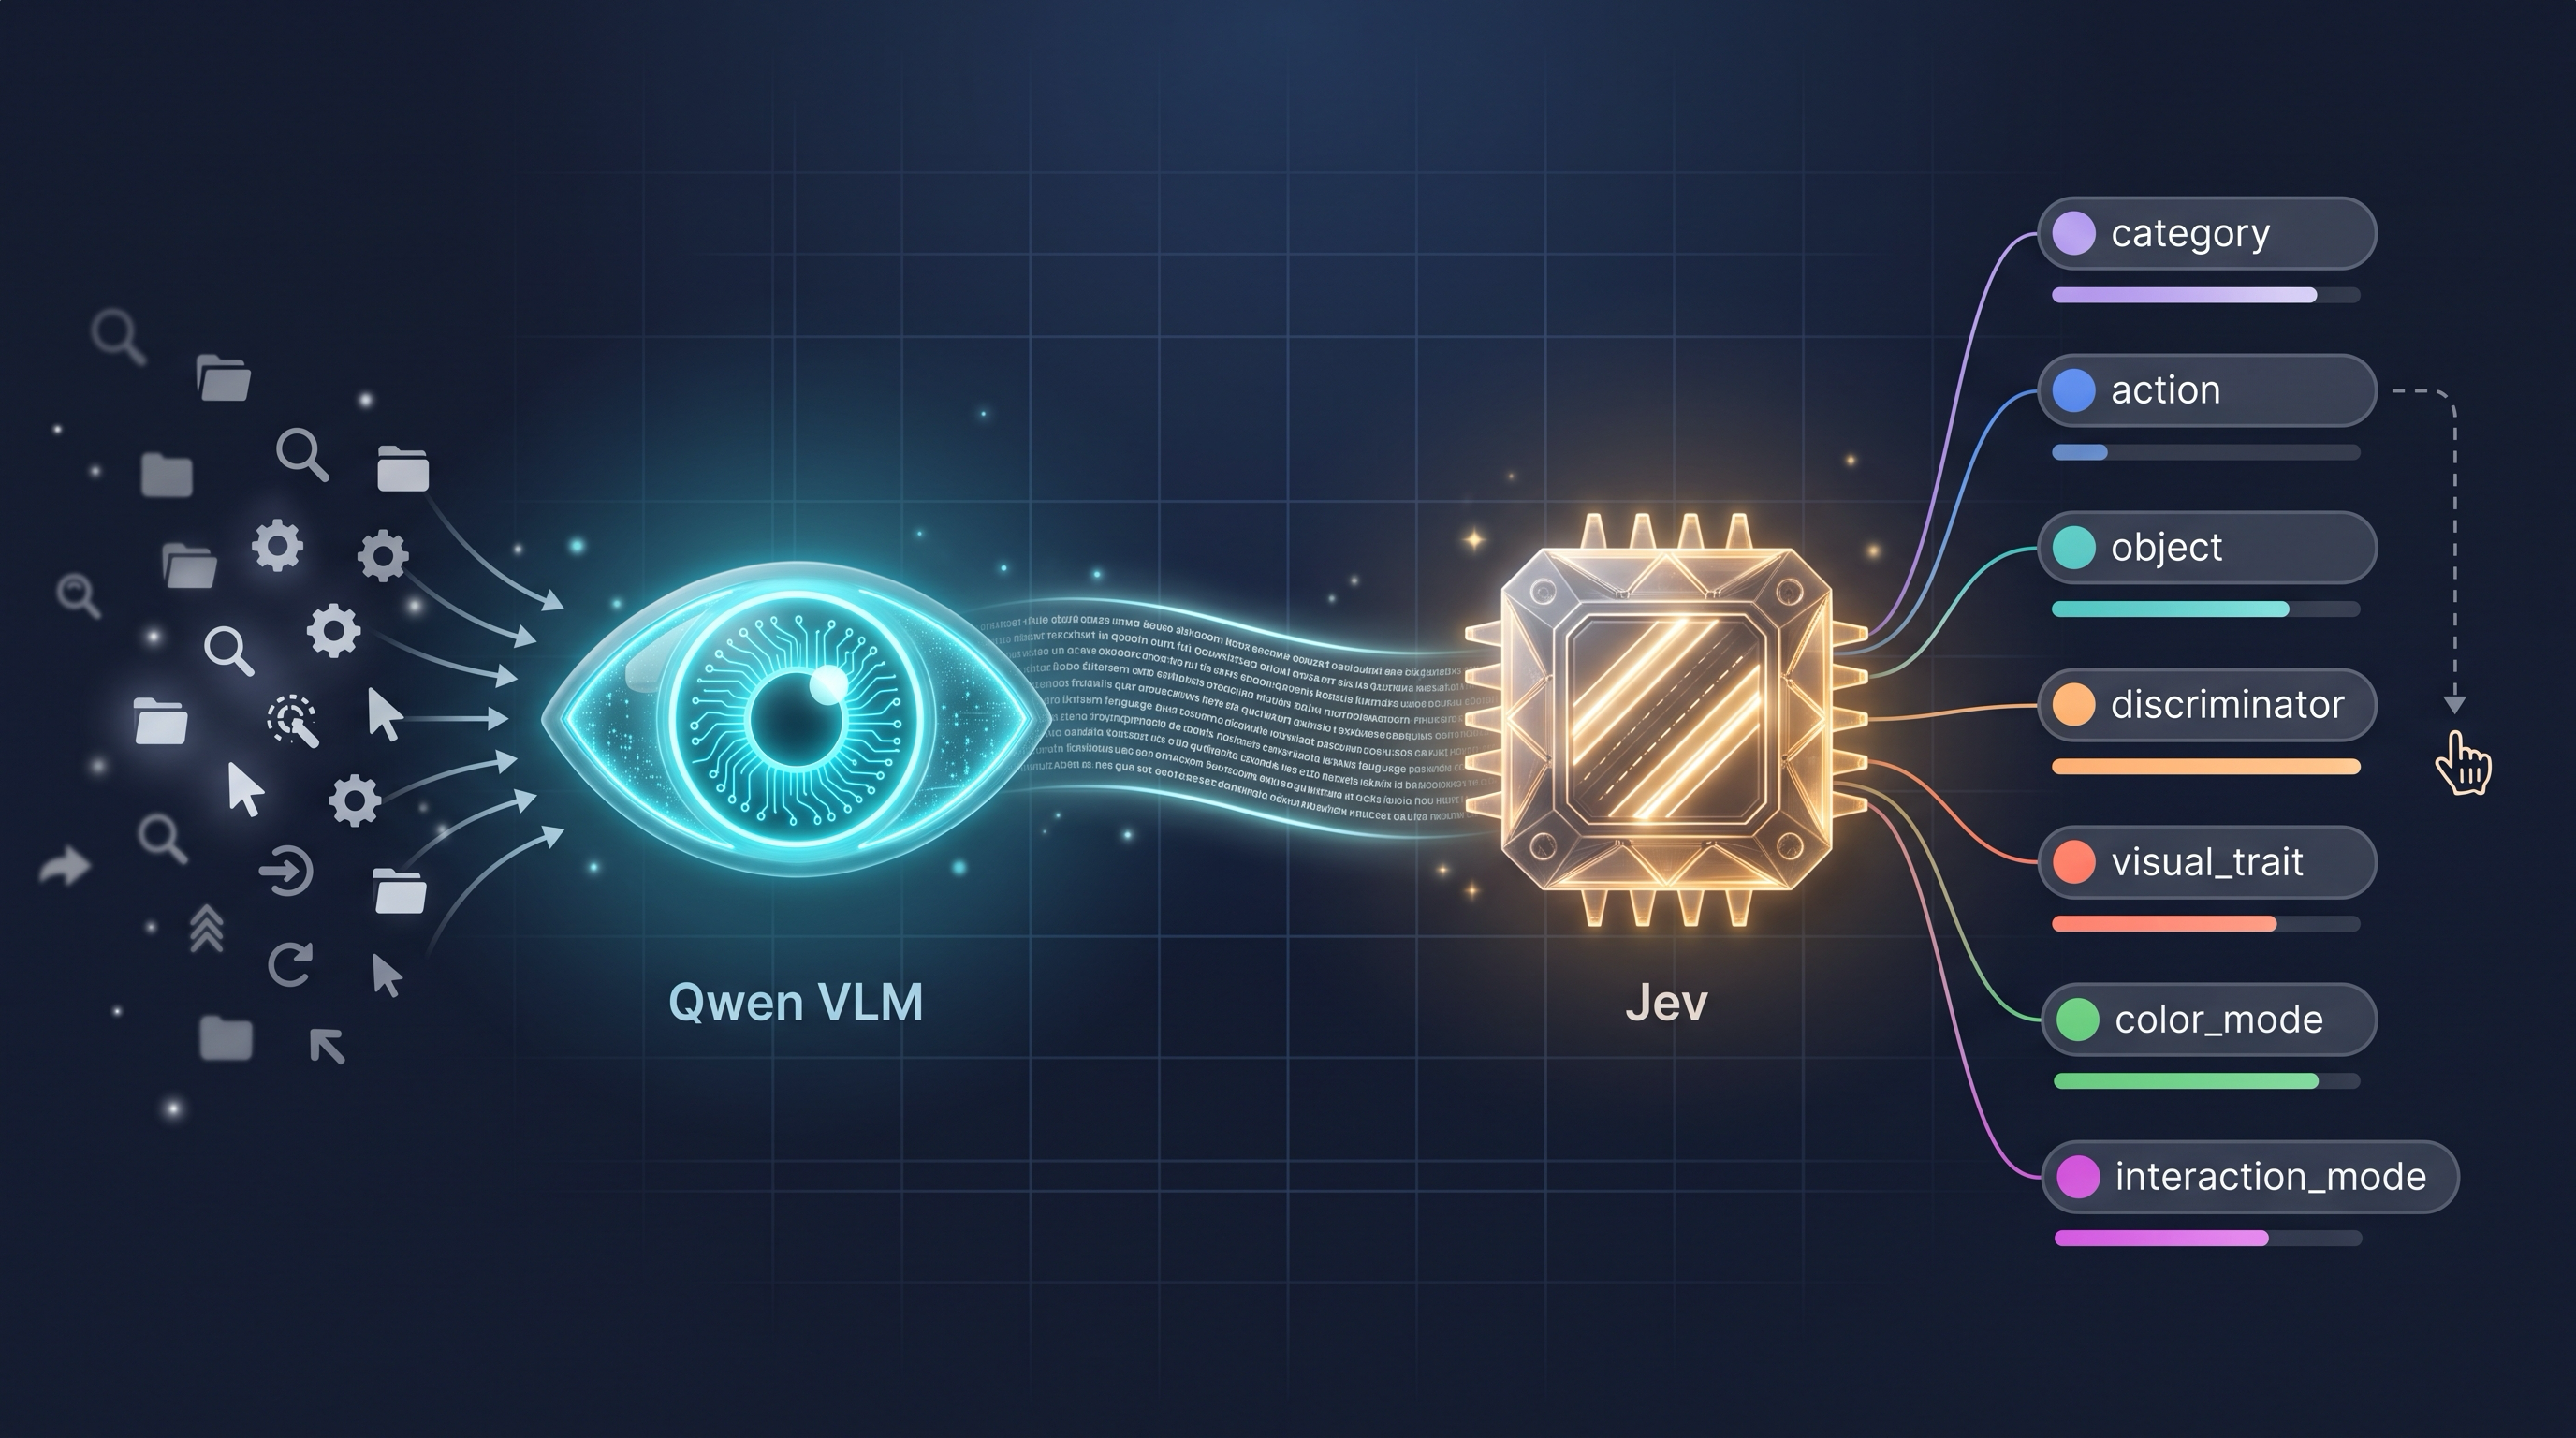
The fix was a re-architecture, not a better prompt. The job is now split — a local VLM perceives (describes the icon in prose), and a new kind of model, a System One decision engine, decides (assigns tags with calibrated probabilities).
TL;DR
- The zero-shot pipeline (a 27B VLM generating all facets in one pass) works, and after RLHF its token logprobs are too overconfident to use as confidence — so we sampled each icon 5 times and voted.
- Voting agreement has only 5 possible values, 3 usable thresholds — and at near-identical agreement, correctness runs 92.5% on
discriminatorand 27.6% onaction. It is a broken confidence signal, structurally — not a tuning problem. - Three more structural faults: cross-facet interference in autoregressive output, a fixed thinking budget diluted across 7 facets, and a 7×5=35-pass cost explosion if you try to fix interference by splitting.
- The new architecture: perception and decision are now different models. A local VLM writes a segmented natural-language description; Jev, the first "System One" model, scores all 7 facets against the full vocabulary in one parallel forward pass, each facet isolated, with calibrated confidence.
- Deterministic routing closes the loop: high-confidence facets auto-commit, low-confidence ones go to a designer — with the full probability distribution, not a single guess, to review.
1. The zero-shot VLM, as promised
Here is the system Part 1 promised, exactly as it ran in production.
The model is Qwen3.8-27B — specifically lued/Qwen3.8-27B-INT8-W8A16-MTP, a weight-only INT8 build (8-bit weights, 16-bit activations) with multi-token prediction for faster decoding. The quantization is a hardware decision, not a cost corner: the production cluster is Ampere-generation GPUs, which have no FP8 tensor cores, so the FP8 and NVFP4 variants of the same model were non-starters there. INT8 weights plus an FP8 KV cache is as far as that silicon can be pushed.
vLLM serves it: every icon enters one continuously-batched job, tensor-parallel across 8 GPUs in production (2 on the dev box). Prefix caching earns its keep here — the system prompt, carrying the tagging rules and the full seven-facet glossary, measures about 5,000 tokens at the long end (100 of them image tokens), and the 9,216-token context was deliberately sized as longest prompt plus 4,096 output plus a sliver of headroom. The prompt is identical for every icon, so it is prefilled once and reused 3,137 times.
Each icon gets one generation: look, think (Qwen3-style reasoning, stripped before parsing), then emit a single JSON object carrying all seven facets — plus, incidentally, a plain-text description of what the model saw. Remember that field; it earns a starring role in section 6. The vocabulary itself grew after Part 1: color_mode joined the original six facets.
And because a single generation at temperature 1.0 is a roll of the dice, we rolled five: n=5, top_p=0.95, majority vote per facet, and an agreement score — votes over five.
The first production run's ledger: 3,137 icons, five generations apiece, in about three and a half hours of active inference — roughly four seconds per icon. Of the 15,685 samples, exactly three came back unparseable — the model thought past max_tokens and the JSON never closed — on three icons: LockPartial, PhoneCallSecurity, and SandboxSettings. Each still had four valid votes, so majority voting papered over the hole, silently. Truncation returns in section 4; the silence is part of the story.
2. Voting was a workaround, not a feature
Section 1 presented n=5 and voting as if they were design choices. They were not; they are a detour, and the closed road that forced it is worth understanding, because it sets up everything that follows.
An autoregressive model ships with an obvious confidence signal: the logprobs of the tokens it emits. In principle a token drawn at 0.99 deserves more trust than one drawn at 0.55, and a routing threshold — auto-commit above, human review below — is just a line drawn between them. In practice, alignment training ruins this. RLHF-style reward models favor answers that sound sure, so the model learns to sound sure; the emitted probabilities stop tracking truth and collapse toward 1.0. The overconfidence is severe enough that a wrong answer's logprobs are routinely indistinguishable from a right one's. What a routing system needs is a model that says "I don't know"; what an aligned generator is trained never to say is "I don't know."
With logprobs off the table, we reached for the statistician's fallback: if you cannot trust one draw, sample the distribution. Five generations per icon at temperature 1.0, a majority vote per facet, and agreement — votes over five — standing in for confidence. Frequency replaces probability.
The price is structural. Five generations where one should do — five times the decode work, five times the KV-cache churn — to purchase a single number. Continuous batching is what makes the tax survivable, and also what hides it: roughly four seconds per icon feels tolerable until you remember that four of every five generations are spent manufacturing that number. The next section is where I have to confess what the number turned out to be worth.
3. Agreement is a broken confidence signal
This is the heart of the post, so let me start with the number that ended the argument. The latest benchmark run — 134 labeled icons, 670 of 670 samples valid — reports, for every facet, how often the five samples agree with each other, and how often the majority vote actually matches the designer's label:
Read rows two and three together. action agrees with itself more often than discriminator does — 94.3% versus 93.6% — and is right less than a third as often. Agreement is doing exactly what it measures and nothing else: it reports self-consistency. From the inside, a model that is reliably wrong looks identical to a model that is reliably right. Voting cannot tell those two machines apart, because the vote is cast by the same machine that made the guess.
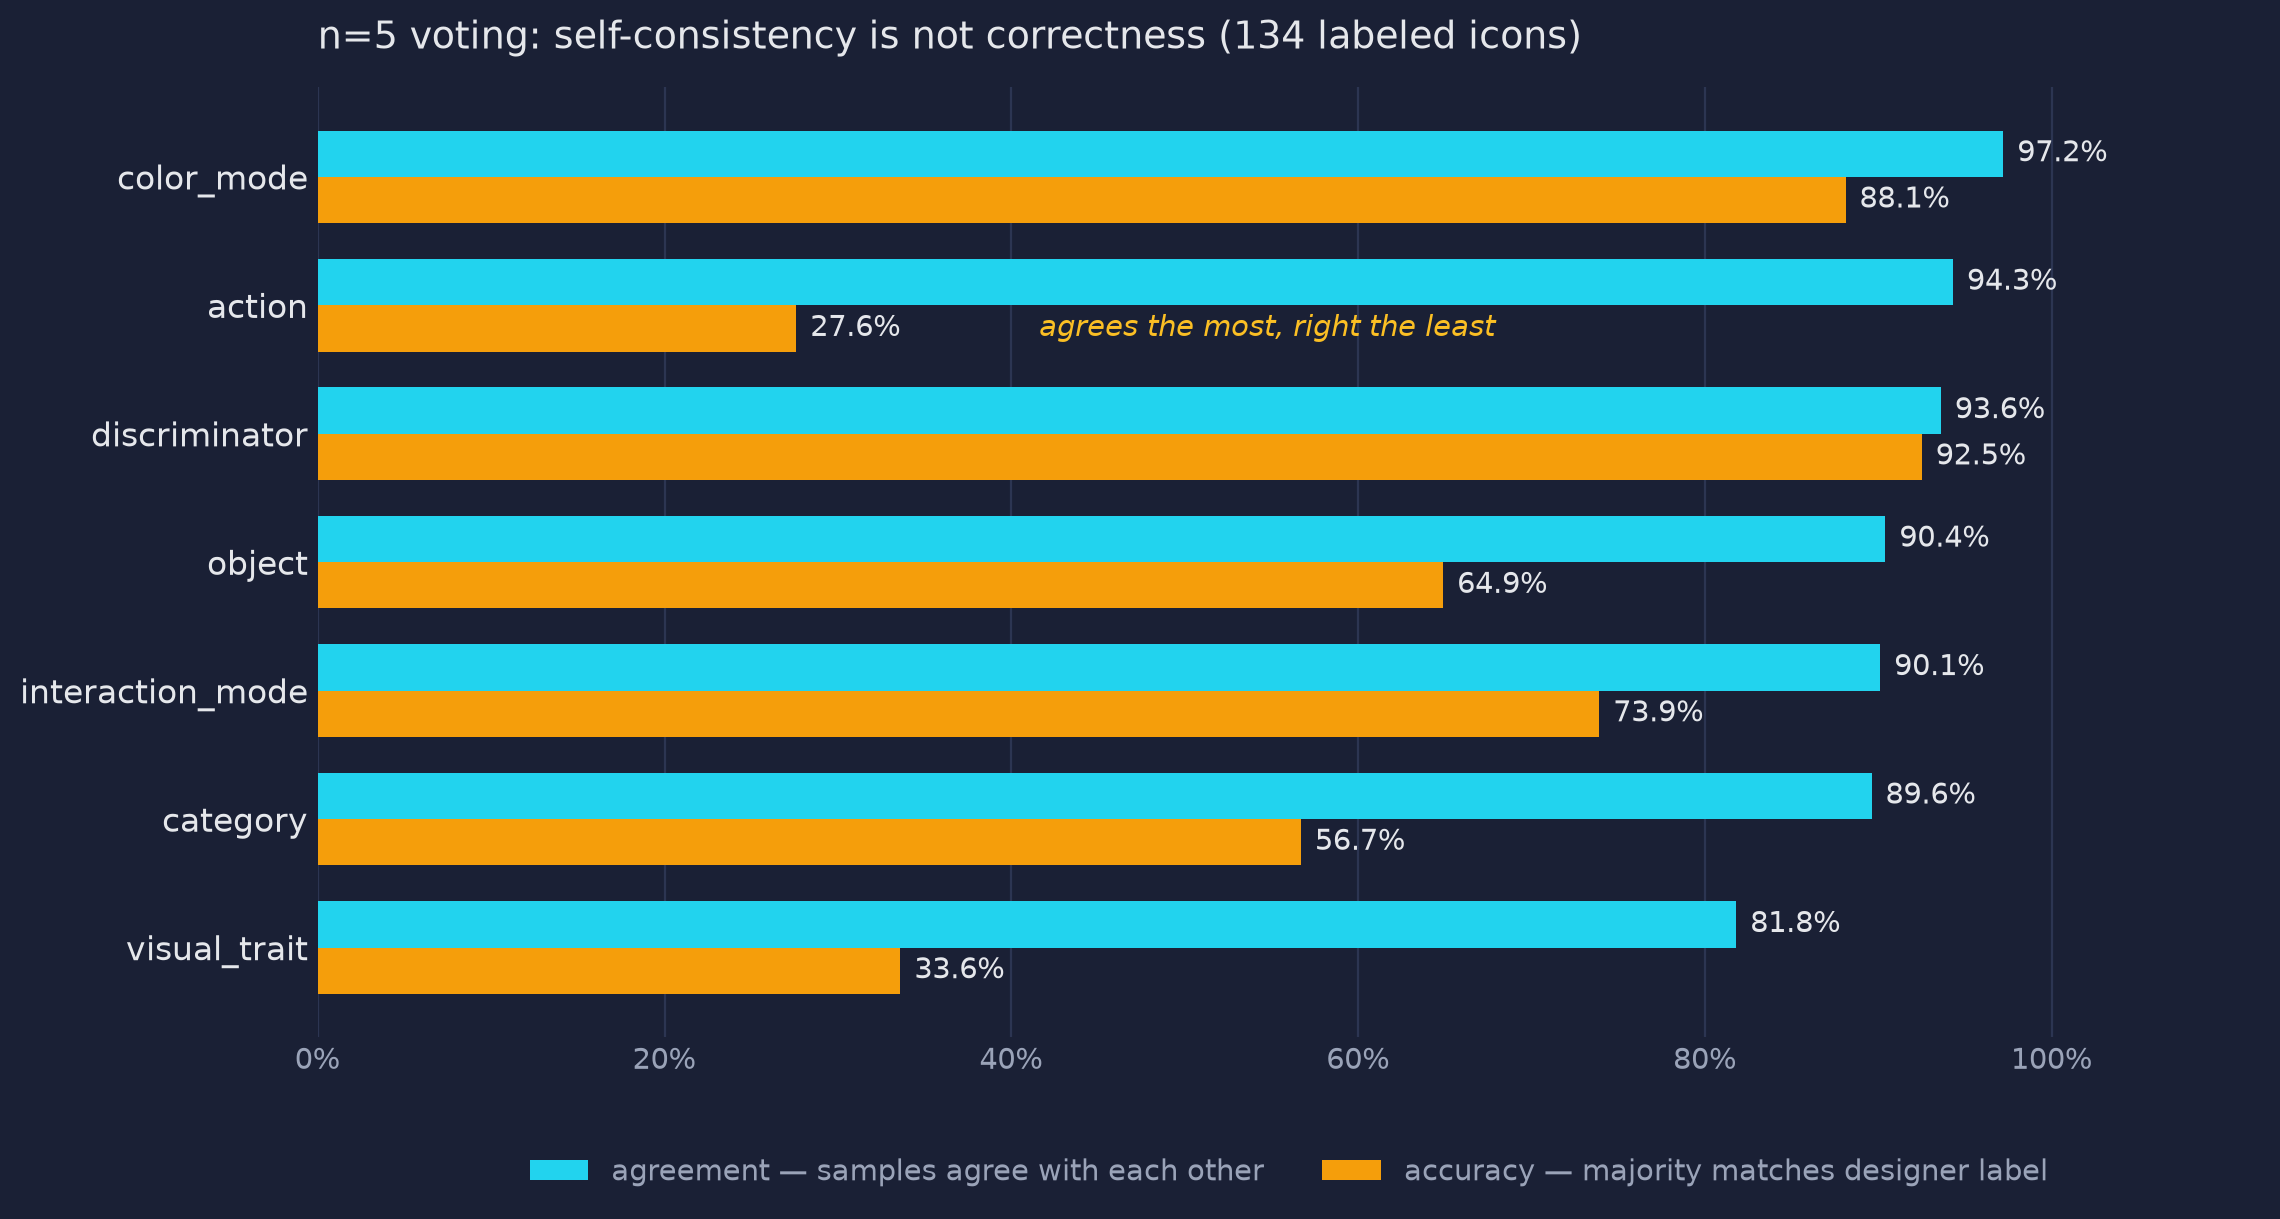
So agreement is not correctness. The three structural failures below are why it cannot even be used as if it were:
Five values, three usable thresholds. can only be , and most icons pile up at the top, so the thresholds that actually separate anything are only , , . There is no knob between them: a business goal like "88% automation at 95% precision" is mathematically inexpressible. The dial has three settings, and the middle one does not exist.
The same threshold means different things on different facets. A routing threshold is one number pointed at seven different dials. As the table above shows, facets running at near-identical agreement carry wildly different reliability — so any single setting either lets action's wrong tags straight into the library, or sits so high that half the icon set lands in human review. A unified routing criterion has to mean the same thing everywhere it is applied. Agreement cannot.
Too coarse to rank, or to offer a shortlist. To be fair, the runner-up votes are not lost — evaluation.py persists full counts and unique_values, so margins are computable. The problem is resolution: with n=5, margin can only take six values. Five samples voting [tools, tools, tools, 3d, 3d] give margin 0.2 whether the true distribution is a coin flip (must go to review) or a robust 0.58-vs-0.12 lead (safe to auto-accept). Entropy is worse: estimating entropy over 29 (category) to 95 (object) classes from 5 samples yields bias larger than the signal. So the system cannot even hand designers a reliable "pick one of these two" shortlist.
4. Three more faults that prompting cannot fix
Cross-facet interference. One generation produces all 7 facets sequentially; the causal attention mask means every earlier facet becomes context for the later ones. Hesitation or hallucination on facet 1 cascades. The facets were designed to be independent — the generation is not.
A diluted, unobservable thinking budget. reasoning_effort="medium" and max_tokens=4096 cover both "understand the drawing" and "decide 7 facets". Facets late in the sequence get whatever budget is left. The 3 nulls in the first 3,137-icon run are direct evidence of truncation on hard icons. And note what agreement cannot see here: all 5 samples of a hard icon face the same budget, so they can converge — "consistently under-thought, consistently wrong". Sampling consistency and thinking sufficiency are orthogonal. Worse, reasoning-token length was never recorded, so the truncation rate is currently unmeasurable — and you cannot tune what you cannot see.
The 35-pass explosion. The obvious fix for interference — score each facet in its own generation — multiplies cost: 7 facets × 5 samples = 35 generative passes per icon. Unacceptable in a production pipeline, however good the batching.
5. A different kind of model: System One
In September 2026, TypeSafe AI released Jev, which they call the first "System One" model. The name is a nod to Kahneman. Software is full of judgments that are, in his terms, System 1 — fast, intuitive calls like which team gets this ticket, is this refund justified, which tag fits this icon. We have been running all of them on System 2 machinery: generative models built to deliberate in prose. Jev is built for the fast calls instead.
Mechanically it is less like a chatbot and more like a typed function. You send a state — any text carrying the context — and typed questions: choice (pick one option from a described list), noul (a yes/no probability), score (a value against a rubric). A single forward pass scores every question in parallel. Nothing is generated, so there are no output tokens — which is why pricing reads like a database's, not a model's: $0.042 per million input tokens, output free.
The property that ended our search: the answers come back calibrated. Each choice returns the full probability distribution across every option, plus a confidence derived from that distribution, and the model is trained so those probabilities align with outcomes — it knows when it doesn't know. That is precisely the property alignment training destroys in a generator's logprobs, and here it comes without sampling tricks: no n=5, no voting. The distribution is the answer, and margins, entropy, and top-k fall out of it as real numbers instead of five-vote shadows.
The constraints, verified against the docs: up to 255 options per choice question; 64k tokens per request, with a 32k cap across the state and the longest single question; and text-only input — no images, no audio.
That last limit sounds like a disqualifier for a vision task. It turned out to be the forcing function for the whole redesign.
6. The new pipeline: the VLM perceives, Jev decides
%3btext-align:center%3b%7d%23mermaid-0 .edgeLabel p%7bbackground-color:rgba(232%2c232%2c232%2c 0.8)%3b%7d%23mermaid-0 .edgeLabel rect%7bopacity:0.5%3bbackground-color:rgba(232%2c232%2c232%2c 0.8)%3bfill:rgba(232%2c232%2c232%2c 0.8)%3b%7d%23mermaid-0 .labelBkg%7bbackground-color:rgba(232%2c 232%2c 232%2c 0.5)%3b%7d%23mermaid-0 .cluster rect%7bfill:%23ffffde%3bstroke:%23aaaa33%3bstroke-width:1px%3b%7d%23mermaid-0 .cluster text%7bfill:%23333%3b%7d%23mermaid-0 .cluster span%7bcolor:%23333%3b%7d%23mermaid-0 div.mermaidTooltip%7bposition:absolute%3btext-align:center%3bmax-width:200px%3bpadding:2px%3bfont-family:arial%2csans-serif%3bfont-size:12px%3bbackground:hsl(80%2c 100%25%2c 96.2745098039%25)%3bborder:1px solid %23aaaa33%3bborder-radius:2px%3bpointer-events:none%3bz-index:100%3b%7d%23mermaid-0 .flowchartTitleText%7btext-anchor:middle%3bfont-size:18px%3bfill:%23333%3b%7d%23mermaid-0 rect.text%7bfill:none%3bstroke-width:0%3b%7d%23mermaid-0 .icon-shape%2c%23mermaid-0 .image-shape%7bbackground-color:rgba(232%2c232%2c232%2c 0.8)%3btext-align:center%3b%7d%23mermaid-0 .icon-shape p%2c%23mermaid-0 .image-shape p%7bbackground-color:rgba(232%2c232%2c232%2c 0.8)%3bpadding:2px%3b%7d%23mermaid-0 .icon-shape .label rect%2c%23mermaid-0 .image-shape .label rect%7bopacity:0.5%3bbackground-color:rgba(232%2c232%2c232%2c 0.8)%3bfill:rgba(232%2c232%2c232%2c 0.8)%3b%7d%23mermaid-0 .label-icon%7bdisplay:inline-block%3bheight:1em%3boverflow:visible%3bvertical-align:-0.125em%3b%7d%23mermaid-0 .node .label-icon path%7bfill:currentColor%3bstroke:revert%3bstroke-width:revert%3b%7d%23mermaid-0 .node .neo-node%7bstroke:%239370DB%3b%7d%23mermaid-0 %5bdata-look='neo'%5d.node rect%2c%23mermaid-0 %5bdata-look='neo'%5d.cluster rect%2c%23mermaid-0 %5bdata-look='neo'%5d.node polygon%7bstroke:%239370DB%3bfilter:drop-shadow(1px 2px 2px rgba(185%2c 185%2c 185%2c 1))%3b%7d%23mermaid-0 %5bdata-look='neo'%5d.swimlane.cluster rect%7bfilter:none%3b%7d%23mermaid-0 %5bdata-look='neo'%5d.node path%7bstroke:%239370DB%3bstroke-width:1px%3b%7d%23mermaid-0 %5bdata-look='neo'%5d.node .outer-path%7bfilter:drop-shadow(1px 2px 2px rgba(185%2c 185%2c 185%2c 1))%3b%7d%23mermaid-0 %5bdata-look='neo'%5d.node .neo-line path%7bstroke:%239370DB%3bfilter:none%3b%7d%23mermaid-0 %5bdata-look='neo'%5d.node circle%7bstroke:%239370DB%3bfilter:drop-shadow(1px 2px 2px rgba(185%2c 185%2c 185%2c 1))%3b%7d%23mermaid-0 %5bdata-look='neo'%5d.node circle .state-start%7bfill:black%3b%7d%23mermaid-0 %5bdata-look='neo'%5d.icon-shape .icon%7bfill:%239370DB%3bfilter:drop-shadow(1px 2px 2px rgba(185%2c 185%2c 185%2c 1))%3b%7d%23mermaid-0 %5bdata-look='neo'%5d.icon-shape .icon-neo path%7bstroke:%239370DB%3bfilter:drop-shadow(1px 2px 2px rgba(185%2c 185%2c 185%2c 1))%3b%7d%23mermaid-0 :root%7b--mermaid-font-family:arial%2csans-serif%3b%7d%3c/style%3e%3cg%3e%3cmarker id='mermaid-0_flowchart-v2-pointEnd' class='marker flowchart-v2' viewBox='0 0 10 10' refX='5' refY='5' markerUnits='userSpaceOnUse' markerWidth='8' markerHeight='8' orient='auto'%3e%3cpath d='M 0 0 L 10 5 L 0 10 z' class='arrowMarkerPath' style='stroke-width: 1%3b stroke-dasharray: 1%2c 0%3b'/%3e%3c/marker%3e%3cmarker id='mermaid-0_flowchart-v2-pointStart' class='marker flowchart-v2' viewBox='0 0 10 10' refX='4.5' refY='5' markerUnits='userSpaceOnUse' markerWidth='8' markerHeight='8' orient='auto'%3e%3cpath d='M 0 5 L 10 10 L 10 0 z' class='arrowMarkerPath' style='stroke-width: 1%3b stroke-dasharray: 1%2c 0%3b'/%3e%3c/marker%3e%3cmarker id='mermaid-0_flowchart-v2-pointEnd-margin' class='marker flowchart-v2' viewBox='0 0 11.5 14' refX='11.5' refY='7' markerUnits='userSpaceOnUse' markerWidth='10.5' markerHeight='14' orient='auto'%3e%3cpath d='M 0 0 L 11.5 7 L 0 14 z' class='arrowMarkerPath' style='stroke-width: 0%3b stroke-dasharray: 1%2c 0%3b'/%3e%3c/marker%3e%3cmarker id='mermaid-0_flowchart-v2-pointStart-margin' class='marker flowchart-v2' viewBox='0 0 11.5 14' refX='1' refY='7' markerUnits='userSpaceOnUse' markerWidth='11.5' markerHeight='14' orient='auto'%3e%3cpolygon points='0%2c7 11.5%2c14 11.5%2c0' class='arrowMarkerPath' style='stroke-width: 0%3b stroke-dasharray: 1%2c 0%3b'/%3e%3c/marker%3e%3cmarker id='mermaid-0_flowchart-v2-circleEnd' class='marker flowchart-v2' viewBox='0 0 10 10' refX='11' refY='5' markerUnits='userSpaceOnUse' markerWidth='11' markerHeight='11' orient='auto'%3e%3ccircle cx='5' cy='5' r='5' class='arrowMarkerPath' style='stroke-width: 1%3b stroke-dasharray: 1%2c 0%3b'/%3e%3c/marker%3e%3cmarker id='mermaid-0_flowchart-v2-circleStart' class='marker flowchart-v2' viewBox='0 0 10 10' refX='-1' refY='5' markerUnits='userSpaceOnUse' markerWidth='11' markerHeight='11' orient='auto'%3e%3ccircle cx='5' cy='5' r='5' class='arrowMarkerPath' style='stroke-width: 1%3b stroke-dasharray: 1%2c 0%3b'/%3e%3c/marker%3e%3cmarker id='mermaid-0_flowchart-v2-circleEnd-margin' class='marker flowchart-v2' viewBox='0 0 10 10' refY='5' refX='12.25' markerUnits='userSpaceOnUse' markerWidth='14' markerHeight='14' orient='auto'%3e%3ccircle cx='5' cy='5' r='5' class='arrowMarkerPath' style='stroke-width: 0%3b stroke-dasharray: 1%2c 0%3b'/%3e%3c/marker%3e%3cmarker id='mermaid-0_flowchart-v2-circleStart-margin' class='marker flowchart-v2' viewBox='0 0 10 10' refX='-2' refY='5' markerUnits='userSpaceOnUse' markerWidth='14' markerHeight='14' orient='auto'%3e%3ccircle cx='5' cy='5' r='5' class='arrowMarkerPath' style='stroke-width: 0%3b stroke-dasharray: 1%2c 0%3b'/%3e%3c/marker%3e%3cmarker id='mermaid-0_flowchart-v2-crossEnd' class='marker cross flowchart-v2' viewBox='0 0 11 11' refX='12' refY='5.2' markerUnits='userSpaceOnUse' markerWidth='11' markerHeight='11' orient='auto'%3e%3cpath d='M 1%2c1 l 9%2c9 M 10%2c1 l -9%2c9' class='arrowMarkerPath' style='stroke-width: 2%3b stroke-dasharray: 1%2c 0%3b'/%3e%3c/marker%3e%3cmarker id='mermaid-0_flowchart-v2-crossStart' class='marker cross flowchart-v2' viewBox='0 0 11 11' refX='-1' refY='5.2' markerUnits='userSpaceOnUse' markerWidth='11' markerHeight='11' orient='auto'%3e%3cpath d='M 1%2c1 l 9%2c9 M 10%2c1 l -9%2c9' class='arrowMarkerPath' style='stroke-width: 2%3b stroke-dasharray: 1%2c 0%3b'/%3e%3c/marker%3e%3cmarker id='mermaid-0_flowchart-v2-crossEnd-margin' class='marker cross flowchart-v2' viewBox='0 0 15 15' refX='17.7' refY='7.5' markerUnits='userSpaceOnUse' markerWidth='12' markerHeight='12' orient='auto'%3e%3cpath d='M 1%2c1 L 14%2c14 M 1%2c14 L 14%2c1' class='arrowMarkerPath' style='stroke-width: 2.5%3b'/%3e%3c/marker%3e%3cmarker id='mermaid-0_flowchart-v2-crossStart-margin' class='marker cross flowchart-v2' viewBox='0 0 15 15' refX='-3.5' refY='7.5' markerUnits='userSpaceOnUse' markerWidth='12' markerHeight='12' orient='auto'%3e%3cpath d='M 1%2c1 L 14%2c14 M 1%2c14 L 14%2c1' class='arrowMarkerPath' style='stroke-width: 2.5%3b stroke-dasharray: 1%2c 0%3b'/%3e%3c/marker%3e%3cg class='root'%3e%3cg class='clusters'/%3e%3cg class='edgePaths'%3e%3cpath d='M247.203%2c121.672L251.37%2c121.672C255.536%2c121.672%2c263.87%2c121.672%2c271.536%2c121.672C279.203%2c121.672%2c286.203%2c121.672%2c289.703%2c121.672L293.203%2c121.672' id='mermaid-0-L_icon_vlm_0' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' style='%3b' data-edge='true' data-et='edge' data-id='L_icon_vlm_0' data-points='W3sieCI6MjQ3LjIwMzEyNSwieSI6MTIxLjY3MTg3NX0seyJ4IjoyNzIuMjAzMTI1LCJ5IjoxMjEuNjcxODc1fSx7IngiOjI5Ny4yMDMxMjUsInkiOjEyMS42NzE4NzV9XQ==' data-look='classic' marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)'/%3e%3cpath d='M451.484%2c121.672L455.651%2c121.672C459.818%2c121.672%2c468.151%2c121.672%2c475.818%2c121.672C483.484%2c121.672%2c490.484%2c121.672%2c493.984%2c121.672L497.484%2c121.672' id='mermaid-0-L_vlm_desc_0' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' style='%3b' data-edge='true' data-et='edge' data-id='L_vlm_desc_0' data-points='W3sieCI6NDUxLjQ4NDM3NSwieSI6MTIxLjY3MTg3NX0seyJ4Ijo0NzYuNDg0Mzc1LCJ5IjoxMjEuNjcxODc1fSx7IngiOjUwMS40ODQzNzUsInkiOjEyMS42NzE4NzV9XQ==' data-look='classic' marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)'/%3e%3cpath d='M761.484%2c121.672L765.651%2c121.672C769.818%2c121.672%2c778.151%2c121.672%2c785.818%2c121.672C793.484%2c121.672%2c800.484%2c121.672%2c803.984%2c121.672L807.484%2c121.672' id='mermaid-0-L_desc_payload_0' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' style='%3b' data-edge='true' data-et='edge' data-id='L_desc_payload_0' data-points='W3sieCI6NzYxLjQ4NDM3NSwieSI6MTIxLjY3MTg3NX0seyJ4Ijo3ODYuNDg0Mzc1LCJ5IjoxMjEuNjcxODc1fSx7IngiOjgxMS40ODQzNzUsInkiOjEyMS42NzE4NzV9XQ==' data-look='classic' marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)'/%3e%3cpath d='M1059.609%2c121.672L1063.776%2c121.672C1067.943%2c121.672%2c1076.276%2c121.672%2c1083.943%2c121.672C1091.609%2c121.672%2c1098.609%2c121.672%2c1102.109%2c121.672L1105.609%2c121.672' id='mermaid-0-L_payload_jev_0' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' style='%3b' data-edge='true' data-et='edge' data-id='L_payload_jev_0' data-points='W3sieCI6MTA1OS42MDkzNzUsInkiOjEyMS42NzE4NzV9LHsieCI6MTA4NC42MDkzNzUsInkiOjEyMS42NzE4NzV9LHsieCI6MTEwOS42MDkzNzUsInkiOjEyMS42NzE4NzV9XQ==' data-look='classic' marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)'/%3e%3cpath d='M1348.375%2c121.672L1352.542%2c121.672C1356.708%2c121.672%2c1365.042%2c121.672%2c1372.708%2c121.672C1380.375%2c121.672%2c1387.375%2c121.672%2c1390.875%2c121.672L1394.375%2c121.672' id='mermaid-0-L_jev_route_0' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' style='%3b' data-edge='true' data-et='edge' data-id='L_jev_route_0' data-points='W3sieCI6MTM0OC4zNzUsInkiOjEyMS42NzE4NzV9LHsieCI6MTM3My4zNzUsInkiOjEyMS42NzE4NzV9LHsieCI6MTM5OC4zNzUsInkiOjEyMS42NzE4NzV9XQ==' data-look='classic' marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)'/%3e%3cpath d='M1594.192%2c90.145L1605.689%2c85.733C1617.185%2c81.321%2c1640.179%2c72.496%2c1658.141%2c68.084C1676.104%2c63.672%2c1689.036%2c63.672%2c1695.503%2c63.672L1701.969%2c63.672' id='mermaid-0-L_route_auto_0' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' style='%3b' data-edge='true' data-et='edge' data-id='L_route_auto_0' data-points='W3sieCI6MTU5NC4xOTIzMDA1MDgwNjk0LCJ5Ijo5MC4xNDU0MjU1MDgwNjkzNH0seyJ4IjoxNjYzLjE3MTg3NSwieSI6NjMuNjcxODc1fSx7IngiOjE3MDUuOTY4NzUsInkiOjYzLjY3MTg3NX1d' data-look='classic' marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)'/%3e%3cpath d='M1594.192%2c153.198L1605.689%2c157.611C1617.185%2c162.023%2c1640.179%2c170.847%2c1657.251%2c175.26C1674.323%2c179.672%2c1685.474%2c179.672%2c1691.049%2c179.672L1696.625%2c179.672' id='mermaid-0-L_route_human_0' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' style='%3b' data-edge='true' data-et='edge' data-id='L_route_human_0' data-points='W3sieCI6MTU5NC4xOTIzMDA1MDgwNjk0LCJ5IjoxNTMuMTk4MzI0NDkxOTMwNjZ9LHsieCI6MTY2My4xNzE4NzUsInkiOjE3OS42NzE4NzV9LHsieCI6MTcwMC42MjUsInkiOjE3OS42NzE4NzV9XQ==' data-look='classic' marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)'/%3e%3c/g%3e%3cg class='edgeLabels'%3e%3cg class='edgeLabel'%3e%3cg class='label' data-id='L_icon_vlm_0' transform='translate(0%2c 0)'%3e%3cforeignObject width='0' height='0'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' class='labelBkg' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='edgeLabel'%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel'%3e%3cg class='label' data-id='L_vlm_desc_0' transform='translate(0%2c 0)'%3e%3cforeignObject width='0' height='0'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' class='labelBkg' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='edgeLabel'%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel'%3e%3cg class='label' data-id='L_desc_payload_0' transform='translate(0%2c 0)'%3e%3cforeignObject width='0' height='0'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' class='labelBkg' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='edgeLabel'%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel'%3e%3cg class='label' data-id='L_payload_jev_0' transform='translate(0%2c 0)'%3e%3cforeignObject width='0' height='0'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' class='labelBkg' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='edgeLabel'%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel'%3e%3cg class='label' data-id='L_jev_route_0' transform='translate(0%2c 0)'%3e%3cforeignObject width='0' height='0'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' class='labelBkg' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='edgeLabel'%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel' transform='translate(1663.171875%2c 63.671875)'%3e%3cg class='label' data-id='L_route_auto_0' transform='translate(-12.453125%2c -12)'%3e%3cforeignObject width='24.90625' height='24'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' class='labelBkg' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='edgeLabel'%3e%3cp%3eyes%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel' transform='translate(1663.171875%2c 179.671875)'%3e%3cg class='label' data-id='L_route_human_0' transform='translate(-8.8984375%2c -12)'%3e%3cforeignObject width='17.796875' height='24'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' class='labelBkg' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='edgeLabel'%3e%3cp%3eno%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3c/g%3e%3cg class='nodes'%3e%3cg class='node default' id='mermaid-0-flowchart-icon-0' data-look='classic' transform='translate(127.6015625%2c 121.671875)'%3e%3crect class='basic label-container' style='' x='-119.6015625' y='-27' width='239.203125' height='54'/%3e%3cg class='label' style='' transform='translate(-89.6015625%2c -12)'%3e%3crect/%3e%3cforeignObject width='179.203125' height='24'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='nodeLabel'%3e%3cp%3eIcon PNG %2b name tokens%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='node default' id='mermaid-0-flowchart-vlm-1' data-look='classic' transform='translate(374.34375%2c 121.671875)'%3e%3crect class='basic label-container' style='' x='-77.140625' y='-39' width='154.28125' height='78'/%3e%3cg class='label' style='' transform='translate(-47.140625%2c -24)'%3e%3crect/%3e%3cforeignObject width='94.28125' height='48'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='nodeLabel'%3e%3cp%3eLocal VLM%3cbr /%3edescribe only%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='node default' id='mermaid-0-flowchart-desc-3' data-look='classic' transform='translate(631.484375%2c 121.671875)'%3e%3crect class='basic label-container' style='' x='-130' y='-51' width='260' height='102'/%3e%3cg class='label' style='' transform='translate(-100%2c -36)'%3e%3crect/%3e%3cforeignObject width='200' height='72'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' style='display: table%3b white-space: break-spaces%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b width: 200px%3b'%3e%3cspan class='nodeLabel'%3e%3cp%3eSegmented description%3cbr /%3ebase / discriminator / stack / geometry%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='node default' id='mermaid-0-flowchart-payload-5' data-look='classic' transform='translate(935.546875%2c 121.671875)'%3e%3crect class='basic label-container' style='' x='-124.0625' y='-39' width='248.125' height='78'/%3e%3cg class='label' style='' transform='translate(-94.0625%2c -24)'%3e%3crect/%3e%3cforeignObject width='188.125' height='48'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='nodeLabel'%3e%3cp%3eState %2b 7 choice questions%3cbr /%3efull vocabulary %2b glossary%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='node default' id='mermaid-0-flowchart-jev-7' data-look='classic' transform='translate(1228.9921875%2c 121.671875)'%3e%3crect class='basic label-container' style='' x='-119.3828125' y='-39' width='238.765625' height='78'/%3e%3cg class='label' style='' transform='translate(-89.3828125%2c -24)'%3e%3crect/%3e%3cforeignObject width='178.765625' height='48'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='nodeLabel'%3e%3cp%3eCloud Jev%3cbr /%3eone parallel forward pass%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='node default' id='mermaid-0-flowchart-route-9' data-look='classic' transform='translate(1512.046875%2c 121.671875)'%3e%3cpolygon points='113.671875%2c0 227.34375%2c-113.671875 113.671875%2c-227.34375 0%2c-113.671875' class='label-container' transform='translate(-113.171875%2c 113.671875)'/%3e%3cg class='label' style='' transform='translate(-86.671875%2c -12)'%3e%3crect/%3e%3cforeignObject width='173.34375' height='24'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='nodeLabel'%3e%3cp%3eConfidence %e2%89%a5 threshold%3f%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='node default' id='mermaid-0-flowchart-auto-11' data-look='classic' transform='translate(1798.2109375%2c 63.671875)'%3e%3crect class='basic label-container' style='' x='-92.2421875' y='-27' width='184.484375' height='54'/%3e%3cg class='label' style='' transform='translate(-62.2421875%2c -12)'%3e%3crect/%3e%3cforeignObject width='124.484375' height='24'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='nodeLabel'%3e%3cp%3eAuto-commit tags%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='node default' id='mermaid-0-flowchart-human-13' data-look='classic' transform='translate(1798.2109375%2c 179.671875)'%3e%3crect class='basic label-container' style='' x='-97.5859375' y='-39' width='195.171875' height='78'/%3e%3cg class='label' style='' transform='translate(-67.5859375%2c -24)'%3e%3crect/%3e%3cforeignObject width='135.171875' height='48'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='nodeLabel'%3e%3cp%3eDesigner review%3cbr /%3ewith full distribution%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3c/g%3e%3c/g%3e%3c/g%3e%3cdefs%3e%3cfilter id='mermaid-0-drop-shadow' height='130%25' width='130%25'%3e%3cfeDropShadow dx='4' dy='4' stdDeviation='0' flood-opacity='0.06' flood-color='black'/%3e%3c/filter%3e%3c/defs%3e%3cdefs%3e%3cfilter id='mermaid-0-drop-shadow-small' height='150%25' width='150%25'%3e%3cfeDropShadow dx='2' dy='2' stdDeviation='0' flood-opacity='0.06' flood-color='black'/%3e%3c/filter%3e%3c/defs%3e%3c/svg%3e)
Four steps, one division of labor: the VLM never picks a tag, and Jev never sees a pixel. Each model does only the half of the job it is structurally good at, and every task the old design asked one model to do badly has been moved across the boundary.
Step 1 — perception only (local VLM). Qwen still sees the image and the name tokens, but its whole thinking budget now serves one job: describe what this drawing is, in natural language, no tag vocabulary in the prompt, no choices to make. The description is written in mandatory segments: a base paragraph (the core entity and its strokes), a discriminator paragraph (any small overlaid marker with knockout gaps — or an explicit "none"), a stack paragraph (same-shape offset overlap, if present), and a fallback geometry paragraph for parts whose meaning resists identification (describe the lines, closed or open, symmetry — don't guess a concept).
Two design arguments to carry into the post:
- Why segmentation must happen here: rules like "remove the small mark — does the core meaning survive?" (the
objectvsdiscriminatorarbitration) or "same-shape offset overlap isvisual_trait: stacked, not a discriminator" are cross-facet judgments that need the pixels in hand. Jev scores facets in absolute isolation by construction — it must never be asked to arbitrate between them. Once the description flattens the layers,objectanddiscriminatorend up fighting over the same text. - Why natural language, not
base=/discriminator=keys: key names tempt the VLM to emit vocabulary-style short words (plus), which collapses the description back into implicit tagging — the exact old failure — and throws away the detail Jev needs. Constrain the structure, keep the prose.
Step 2 — assemble the payload. The description becomes the state. Each facet becomes one choice question whose options are the full vocabulary with glossary explanations — the docs explicitly recommend complete lists over shortlists, plus an other / none-of-the-above catch-all, which is exactly our other and empty-string conventions from Part 1. Capacity check against the 255-option and token limits:
other + empty)(All seven facets ship in a single request; the largest facet uses 38% of its per-question limit. One amusing coincidence: the seven candidate lists happen to sum to exactly 256, which is easy to mistake for a tight fit against the 255 cap — but the cap is per question, not per request.)
Step 3 — one parallel pass (cloud Jev). All 7 facets scored in one forward pass, mathematically isolated from each other — no causal mask, no cascade, no shared thinking budget. Each answer arrives as a probability distribution with calibrated confidence. And because Jev is text-only, no image asset ever leaves the building — only a description does.
Step 4 — deterministic routing. Plain code, per facet: confidence above the bar (say 95%) auto-commits; below it, the icon goes to a designer — who now reviews a full distribution (margin, entropy, top-k candidates) instead of a single unexplained guess. The continuous confidence scale makes the threshold an actual dial again, tunable per facet.
7. Old vs new
Where the two designs stand, side by side:
8. Honest limitations
- The compliance trade is real. Descriptions of unreleased icons now leave our perimeter. No image assets, no filenames of consequence — but it is a genuine compromise, decided deliberately, not hand-waved.
- Jev is young. Version 1.13, released September 2026; English best-supported. TypeSafe itself publishes a jaggedness page of known failure modes — literal reading, context rot from bloated state, arithmetic — which is exactly the kind of honesty we want in a vendor, and a checklist our payload already respects: compact state, no math, no generation asked. Still, a calibrated confidence claim is only as good as the model behind it — Part 3 must validate calibration on our facets before any threshold goes live.
- Ceilings exist. 255 options per question and 64k tokens per request are far away today; if a facet outgrows them, the documented path is hierarchical choices with beam search — more moving parts.
- The perception ceiling moved, not vanished. If the VLM's description omits or blurs a layer, Jev's calibration will honestly report low confidence — which is exactly the behavior we want, but it means the description prompt is now the quality ceiling of the system.
What's next
Part 3 will run the new pipeline across the library and answer the only question that matters: does Jev's confidence actually hold calibrated precision on our facets, per facet, at the thresholds the business wants? The benchmark set of hand-labeled icons is waiting.
To be continued...